Researchers claim AI's internal workings may be more understandable than previously thought
Read more
TechCentral
techcentral.co.za

Researchers claim AI's internal workings may be more understandable than previously thought

There is a claim that artificial intelligence models are much simpler to understand than researchers previously believed, which has drawn significant attention in the field of AI safety. However, academics from South Africa warn that these findings have not yet been verified or peer-reviewed.

Nick Kammarata, a researcher at the startup Goodfire who previously worked at OpenAI, puts forward this hypothesis in his document titled 'informal research essay and working hypothesis.' He asserts that 'the canonical evidence of polysemy and superposition, which convinced most of the scientific community, including myself, about the arbitrary packaging of concepts in networks, was misinterpreted.'

He explained to MIT Technology Review: 'We were looking at it wrong.' Stephen Boyke Sidley, an invited professor at Rhodes University, believes that the nature of AI's 'black box,' which even its creators cannot decipher, lies at the heart of many concerns surrounding it.

Sidley noted that 'this caused concern because if you cannot understand how AI thinks, how can you prevent it from doing bad things, such as encouraging someone to commit suicide? That is the essence of what is called AI alignment.' He added that 'Kammarata's paper suggests that there is no such complexity inside the AI's neural network—we were simply looking at it through the wrong lens. His partial and (for now) unverified results are promising because they offer hope that we can make AI a subservient tool rather than the uncontrollable and disobedient child it currently is.'

Cats, cars, and the letter V

The essay examines a well-known example in interpretability—a discipline aimed at figuring out the processes occurring inside AI models. In Google Inception v1 image recognition model from 2014, neuron 4e:55, which activated upon detecting a specific feature, responded to both cats and cars.

In the 2020 paper 'Zoom in,' co-authored by Kammarata as part of a project led by Chris Olah, now head of interpretability research at Anthropic, this neuron was considered a textbook example of mixing unrelated concepts. However, Kammarata now argues that they are linked by the common shape of the letter V: the pointed profile of a cat and the front end of a car viewed at an angle. This same neuron also triggers on the corner of a pool table and the nose of a high-speed train, while round shapes elicit an inverse reaction.

An update to the essay from October 30th emphasizes that the neuron still recognizes cats and cars, with the overall characteristic being the V shape. Kammarata told MIT Technology Review that he only needed five seconds to study the model he had worked on for 'probably thousands of hours.'

He posits that if most neurons perform one primary function, researchers will be able to analyze models without resorting to pre-training a second model to decode them. Preliminary checks of Alibaba's Qwen3-32B model show that approximately 90% of 'neuron polarities'—positive and negative ends of neuron activity—have one main task; about 7% perform two related tasks, and 2–4% are still unexplored, although these figures depend on threshold values. Furthermore, the project he started at OpenAI in 2023 found that only about 1.7% of neurons could be interpreted 'by our most generous estimate.'

Not yet peer-reviewed

Professor Benjamin Rosman, founder of the Institute of Mind at the University of Witwatersrand, who was included in Time magazine's list of the 100 most influential people in AI in 2025, called this an 'interesting and potentially very hopeful development for AI safety.' Nevertheless, he stressed: 'the research has not yet been peer-reviewed, and it is too early to draw strong conclusions about what this means for AI safety.'

Others express greater skepticism. Neil Nanda from Google DeepMind wrote on X that 'this is interesting work, but I don't think it's a significant update to the overall picture of interpretability.' Jacob Hilton from the Alignment Research Center added: 'For full understanding, we need to go beyond individual neurons and explain how they connect to form circuits.'

Rosman concluded that 'even if we become much better at understanding how these systems work, it does not necessarily mean we know how to make them behave safely.'
Similar stories

OpenAI AI Model Solves Navier-Stokes Problem and Presents Research on Mathematical Tasks
Read more
cgtn.com

OpenAI AI Model Solves Navier-Stokes Problem and Presents Research on Mathematical Tasks

OpenAI recently announced that its artificial intelligence model has managed to solve the Navier-Stokes problem, which has posed difficulties for mathematicians for almost a century.

Furthermore, the developers released 722 manuscripts detailing progress in solving 372 mathematical problems.

These discoveries have caused astonishment among mathematicians, who are now questioning how this will affect not only their current work but also the future of their entire profession.

Vignesh Subrahmaniam from Intuit discusses the shift from prompt engineering to building functional artificial intelligence systems
Read more
yourstory.com

Vignesh Subrahmaniam from Intuit discusses the shift from prompt engineering to building functional artificial intelligence systems

In recent years, improving AI performance has depended on the ability to write higher-quality prompts. However, this paradigm is rapidly changing as AI systems begin to reason, make decisions, and perform actions within entire workflows autonomously.

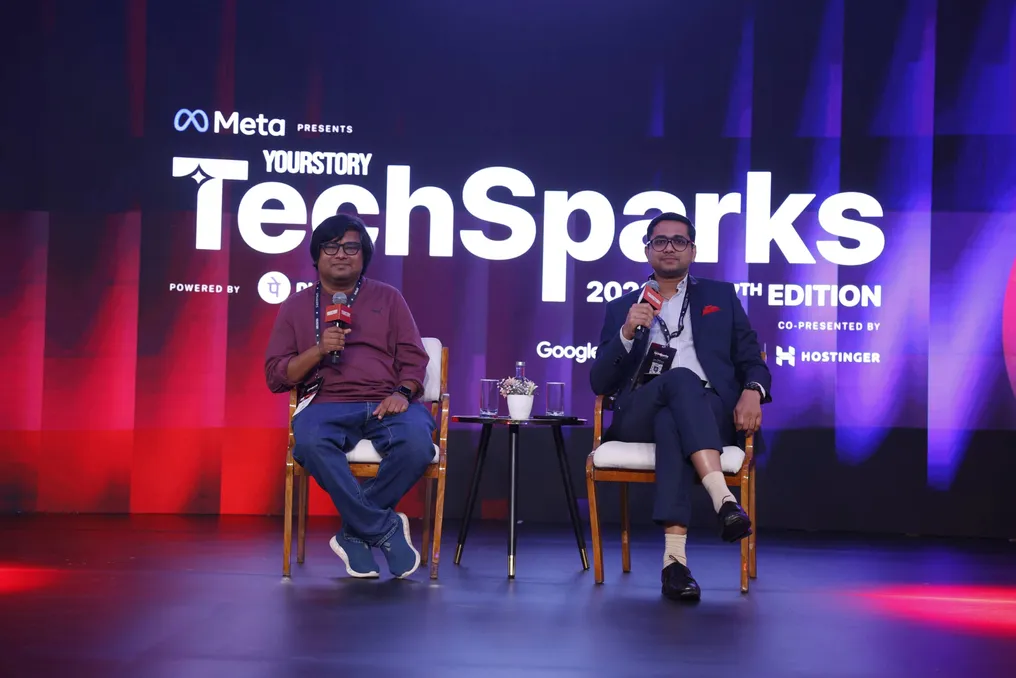
At the TechSparks 2026 event, YourStory's flagship event, Dr. Vignesh Subrahmaniam, an AI lead scientist at Intuit, held a discussion with Aditya Charlie, Editor-in-Chief of YourStory and The CapTable. The discussion, titled 'Beyond the Prompt: Building AI That Thinks, Acts, and Learns,' focused on what developers need to rethink as intelligence becomes increasingly autonomous.

The session began with questions about Subrahmaniam's typical workday and a request to simplify fintech and AI concepts for the audience. He used a chess analogy, asking: if an algorithm is not taught the rules of chess but shown a million completed games with winners, can it deduce both the rules and the most probable winning strategies?

Intuit's team applies a similar approach to support small businesses, as the company serves both consumers and accountants. Subrahmaniam noted: 'We study the game of business by analyzing data, real actions, and the results that enterprises undertake.' The goal is to understand the factors that contribute to business success in customer acquisition, rapid growth, and improved cash flow.

The conversation then shifted to the paradigm shift for developers: moving from years of studying how to write smarter prompts to designing agents given a goal, which they determine the steps to achieve themselves. Subrahmaniam compared prompt engineering to the long history of programming languages, starting from binary code and assembly up to Fortran, C, and Python. Large language models have allowed anyone to program in simple English, but this method has its limitations.

Researchers quickly realized that intelligence should not reside only within the model. The model must act as an orchestrator, breaking down a complex task into a sequence of actions and tool calls. Real intelligence moves into the called tools; and these tools must also be designed differently: 'not so that a human, or a software developer, or anyone else can use them, but in such a way that the LLM orchestrator can actually use them.'

This requires creating highly precise tools with extremely deterministic outcomes. For developers, mastery shifts from clever phrasing to reliable components that the model can call repeatedly without surprises.

Regarding sources of new data, Subrahmaniam openly stated that training on text data is largely solved. The more complex task is training on multimodal sources and real-world actions. He cited the example of how a young child primarily learns through what they see, hear, and observe, rather than reading, asserting that incorporating such real-world signals into AI systems will help models move beyond text generation and start suggesting actions. He called this the next frontier.

When considering regulated industries, he took the audience back 18 years, to one of the first machine learning labs in Bangalore where he worked on logistic regression and multilayer perceptrons. Back then, the biggest problem was not the algorithm itself. He recalled: 'Actually, it was the quality of the data.'

This problem has not changed. Whether a team is training simple regression or fine-tuning a transformer, the principle of 'garbage in, garbage out' remains valid. According to him, companies capable of collecting, aggregating, and storing the highest quality data will gain an advantage.

During a short Q&A session, one participant asked how restrictions on storing financial data affect Intuit's operations. Subrahmaniam named consent as the foundation of any training system and referenced the Framingham study, where residents of Massachusetts were allowed to track their health over time, which shaped the modern understanding of cardiovascular disease. He added that companies are also obligated to explain the benefits of data usage to the general public.

As the conversation concluded, the overarching idea was that as AI transitions from reacting to acting, foundations become more important than interfaces. Prompts will remain a starting point, but the real work now lies in creating robust tools that agents can call, supplying systems with high-quality data, and obtaining the consent that allows them to learn. It is here, beyond the prompt, that the next wave of AI will be won for developers.

Popular