SenseTime releases SenseNova-Loop-9B-Preview model with cyclic architecture
Read more
Pandaily
pandaily.com

SenseTime releases SenseNova-Loop-9B-Preview model with cyclic architecture

SenseTime announced the release of the SenseNova-Loop-9B-Preview model to the public on October 30th. This multimodal model is built on a looped Transformer design and, according to the company, is capable of competing with models around 27 billion parameters while using only 9 billion parameters.

The model weights are available on the Hugging Face platform under the Apache 2.0 license, and the source code is hosted on GitHub. According to the model card, it has 32 distinct decoder layers. The first four and the last four layers are executed once, while the layers from 4 to 27, forming a block of 24 layers, are sequentially executed twice using shared weights. This results in 56 decoder layer executions in a single forward pass, while only storing 32 sets of layer weights.

The decoder alternates between linear and full attention mechanisms: within each group of four layers, there are three layers with linear attention followed by one layer with full attention. The cycle boundaries correspond to these groups. The model accepts text and images as input and generates text as output. Its training recipes utilize sequences up to 262,144 tokens, including text, images, code, and tool trajectories.

Within the loop section, SenseTime integrated two-stream manifold-constrained hyper-connections (mHC). These connections transfer two residual streams and use learned mappings constrained by Synchhorn normalization to mix information between them. The company reports that tests excluding components showed that mHC increased scores on GPQA Diamond by 4.42 points and on TeamBench by 13.34 points.

SenseTime claims that under evaluation conditions, its model outperforms other models in coding, office, and agent tasks, and also surpasses Qwen3.5-27B on the WorkBuddy Bench, RaccoonPPT Bench, and AutomationBench benchmarks. The benchmark graph in the card also presents results for BIRD-Dev, AIDABench, Terminal Bench 2.1, and T3-Banking. This data represents proprietary results from the company, and a technical report is still pending.

The model supports MTP for inference acceleration, while two other acceleration methods—Dspark and Dflash2—are still under training. SenseTime plans to further investigate DSA and adaptive iteration counts to improve efficiency and performance in tasks.
Similar stories

DeepSeek V5 identifiers found in Harness code; V4.1-Flash leads among open models on FrontierCode
Read more
pandaily.com

DeepSeek V5 identifiers found in Harness code; V4.1-Flash leads among open models on FrontierCode

Developers discovered three new model identifiers in DeepSeek's official Harness repository on GitHub: deepseek-v5, deepseek-v5-open, and deepseek-v5-next. Currently, DeepSeek has not announced the V5 model, and these entries are test placeholders in the code, not available models.

Upon checking the repository, it was determined that these identifiers are located in a test file for the DeepSeek account provider, specifically in the file packages/llm/llm-deepseek-account/tests/provider.spec.ts, on lines 154–156, next to the existing deepseek-v4-pro entry. The repository history shows they were added in a commit from September 24th, which moved the DeepSeek account model directory into the official list of models.

The test scenario checks how the client filters models by required version: the v5-open entry requires a minimum client version of 0.0.1, while v5-next requires 99.0.0-alpha.1, and the test expects only the flash and v5-open models to appear in the list. This indicates the possibility of switching to a new model from the Harness server side, either for all clients or only for those who have updated, without needing a new release. However, this does not confirm the existence of the V5 model or its release timeline, and some developers consider these names merely test placeholders. As of October 28th, DeepSeek has made no announcements, model cards, or API identifiers for the V5 series.

The current model lineup includes V4-Pro and V4.1-Flash; the latter was released in September with a new architecture while retaining the V4 name.

In the same week, a new benchmarking result was presented for the current model. Artificial Analysis released Intelligence Index v5, which is the largest update since the V4 release in January, with 60% of the weight now based on closed test datasets or hidden answers. Coding accounts for 25% of the index, and of these 15 points, FrontierCode 2.0 from Cognition accounts for the evaluation of code changes in 132 real open-source tasks to see if they would approve a pull request merge.

On the FrontierCode 2.0 platform, the DeepSeek V4.1-Flash-1017 model scored 28% at maximum effort, which is the highest score among models with released weights. Kimi K3.1 Pro achieved 25.5%, but its full weights are not yet available. Gemini 4 Argon reached 25.7%, and GPT-6 Luna scored 25.2%.

The overall index was less favorable. DeepSeek V4.1-Flash scored 32 points, tying with GLM-5.3, while the leader, Claude Opus 5.5, received 58 points. Artificial Analysis notes that the gap between the best open model with released weights and the leaderboard leader has increased from 3 points under v4.3 to 12 points under v5.

MemTensor releases open-source MemT 1.0 model with memory for preserving long histories
Read more
pandaily.com

MemTensor releases open-source MemT 1.0 model with memory for preserving long histories

The Chinese company MemTensor has introduced and made publicly available a series of models it calls memory-oriented foundation models, named MemT 1.0. This series includes two models: MemT-1.0-Flash, which has a total of 288 billion parameters, of which 17 billion are actively used, and MemT-1.0-Nano, which has 36 billion total parameters and 3 billion active ones.

The weights of these models are available on the Hugging Face platform, and the corresponding code is hosted on GitHub along with a technical report.

The models are designed to solve a common problem associated with long dialogues. Most existing systems store the entire history in the context window, which leads to slowdowns and increased inference costs with every new turn. Instead, MemT integrates a trainable memory module directly into the model.

After each interaction, the model records new information into a fixed memory state and retrieves it when necessary, instead of re-reading the entire previous log every time.

MemTensor reports that the training of the models was conducted in two stages based on 34 billion tokens: first, the model learned to write information into memory, and then it learned to answer questions using this stored information.

Performance Results and Comparison

All presented performance metrics are based on the company's own evaluation. MemTensor claims that end-to-end inference runs approximately 1.86 times faster than the full context approach with a history of 128 thousand tokens, and about 3.99 times faster with 256 thousand tokens.

The time to the first token response is estimated at approximately 104–112 milliseconds for the memory model, compared to approximately 445 milliseconds for full context at 256K. Furthermore, the company notes that the memory state size per session with a 256K history is about 40 MB, which is significantly less than the 5.06 GB required for the full context cache, representing a reduction of approximately 130 times.

On 11 memory benchmarks, MemTensor reports average scores of 50.6 for Flash and 47.0 for Nano. These results place the models first and second among comparable parametric memory methods and roughly match the results of retrieval-augmented approaches on average, even without retrieving history during the query.

The company also emphasizes that adding memory did not degrade the overall capabilities of the Flash model under tests with a high number of distractors.

Developers should note the licensing terms: the repository code is published under the non-commercial PolyForm license, while the model weights have Apache and MIT licenses, respectively.

The team plans further development towards improving long-term memory, increasing memory capacity, and reducing memory update costs, with the long-term goal of creating agents that continue to learn based on their interactions.

VAST releases open-source model EdenLive for rendering simple game frames into detailed video
Read more
pandaily.com

VAST releases open-source model EdenLive for rendering simple game frames into detailed video

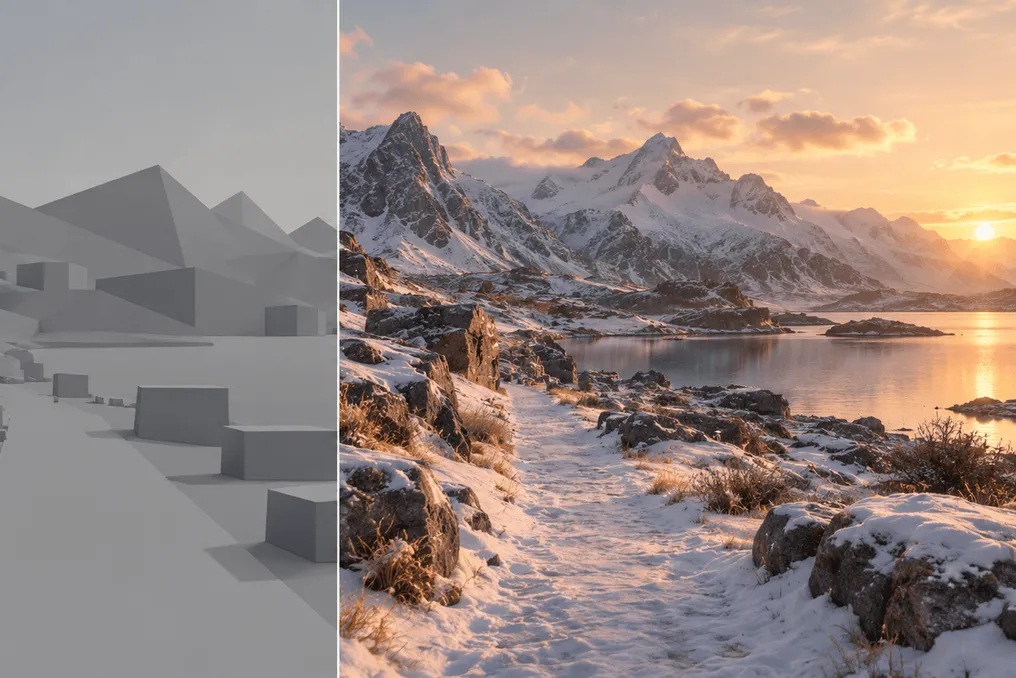
VAST, a company specializing in generative AI in 3D and behind the Tripo platform, has made the EdenLive model publicly available. This model operates in real-time and is capable of taking simplified game frames or existing video, continuously re-rendering them into detailed images in a chosen style, which can range from photorealistic to anime.

The release includes 5B and 14B model weights, code for real-time inference, a technical report, and end-to-end usage demonstrations. It is important to note that EdenLive does not simulate the world on its own; instead, a higher-level program, such as a game engine or code written by a coding agent, is responsible for enforcing rules, tracking world state, and outputting a rough reference video.

After receiving this reference video, EdenLive performs the rendering, guided by the initial frame and a text prompt. VAST asserts that this separation allows game logic to remain explicit and testable, while concentrating the model's limited real-time capabilities solely on the visual appearance.

The approach was first presented in June as part of a larger world research effort known as Project Eden. According to VAST, the 5B model can operate at a frame rate above 24 frames per second at 720p resolution on a single Nvidia RTX 5090 GPU. The README file on GitHub specifies this figure as approximately 24.7 FPS at a resolution of 1280 by 704 pixels, utilizing acceleration from the LightX2V inference framework.

The technical report reports a rate of 29.8 FPS at the same resolution on a single H100, as well as 26.8 FPS at a resolution of 832 by 480 for the 14B model running on eight H100s. VAST states that the total latency from user input to the corresponding frame is in the hundreds of milliseconds, and the system can generate content continuously for several minutes.

Both models are based on the Wan2.2-TI2V-5B and Wan2.1-I2V-14B video models. The inference code and core diffusion, VAE, and decoder weights are distributed under the Apache 2.0 license, although not all components have this license. The visual encoder uses the DINOv3 license, and the image model used in the request-to-game workspace is under the Non-Commercial FLUX License, which restricts the use of this workspace to non-commercial purposes.

VAST also introduced Game Prototype Turbo—a skill that transforms a text prompt into a rough playable game, which EdenLive can then render. VAST demonstrations include a platformer where a character freezes lava to create waypoints, a two-player fighting game where health bars and round timers are tracked by a higher-level system, and video rendering that transforms a person filmed against a blue background into a cartoon character. Furthermore, the model demonstrates replacing human hands with robotic ones in first-person footage to create additional training data for embodied AI.

VAST notes that EdenLive is currently best suited for low-frequency interactions, such as scene inspection and box-pushing puzzles. Fast, intense gameplay, maintaining multi-character consistency, fine control over small objects, and visual stability during long sessions still require refinement.

Popular