ACE Robotics, in collaboration with S-Lab from Nanyang Technological University, has released Mundo—a world model capable of generating an interactive and explorable environment based on a small number of real-world images. This was reported by the Chinese news outlet Robot Pro on October 31.
The team asserts that Mundo can reconstruct a scene, display it from various angles, and simulate it over time, which allows for testing and training robots within a digital copy of a specific space.
According to the GitHub repository, the code and model weights will be available by the end of November.
How Mundo Works
Mundo accepts one to twelve contextual images and generates new views along a specified camera path. When using only a single image, the system extrapolates the visible style and structure to unseen areas, while increasing the number of images reduces uncertainty in unphotographed zones.
For large spaces, the model can generate camera movements lasting from tens of seconds to several minutes, selecting the most appropriate photographs for each segment and overlaying them to ensure consistency.
Technical Details of the Model
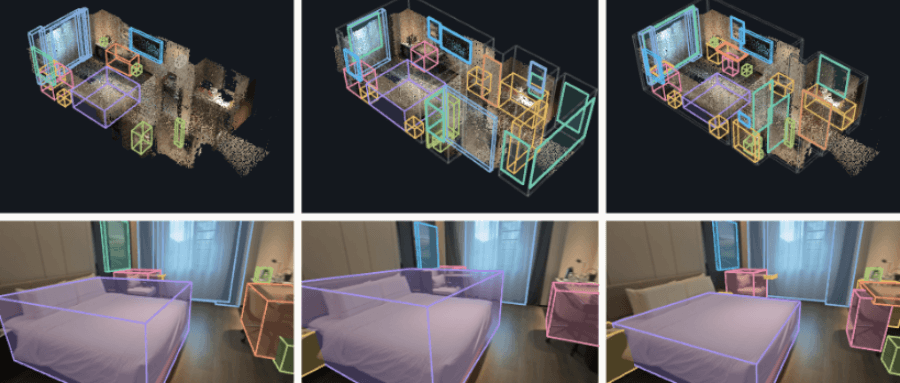
The core functionality relies on a three-dimensional fundamental model that reconstructs camera poses and dense geometry. Simultaneously, a 3D detector creates an initial bounding box for every major object. Since detectors may miss objects or inaccurately estimate their sizes, a vision-and-language-based agent edits the scene program, renders it from each input viewpoint, compares the result with the original photographs, and determines what needs correction. Concurrently, numerical optimization fine-tunes the position, size, and orientation of the boxes.
A separate verification agent monitors consistency without interfering with scene editing. The scene program records the name, pose, size, mass, and friction coefficient of each object. Scripts apply forces and actions, and the physics engine, currently MuJoCo, calculates motion, contact, and collisions. Finally, a video diffusion model visualizes the simulation in the style of the original shots.
The team refined the MiniMax reference-to-video model using approximately 40,000 paired videos of size 640x480, generating clips of 124 frames and reusing the last 34 frames from each clip to maintain continuity in long videos.
Use Cases and Limitations
Demonstrations include scenarios where robots navigate a recreated hotel floor, open a washing machine in a laundry room, place an apple in a bowl, and stack blocks, utilizing views from head and wrist cameras, as well as recorded trajectories.
The team clearly outlined the system's limitations: the reconstruction process takes between 10 and 20 minutes, rendering is performed at approximately 1.5 frames per second on eight A800 GPUs with 20 inference steps. It was also noted that small objects might appear to float, and there is no long-term memory for scenes that change over extended periods.