Study shows large language models are more effective than humans at identifying methodological errors in clinical trials
Read more
N+1
nplus1.ru

Study shows large language models are more effective than humans at identifying methodological errors in clinical trials

Scientists from Canada, Singapore, and the USA conducted a study in which fifteen different large language models were tested. The purpose of the test was to determine the ability of these models to find methodological flaws in scientific publications concerning clinical trials.

The results showed a significant superiority of the models over human experts. On average, large language models were able to detect methodological errors in the range of 53 to 99 percent. Meanwhile, the percentage of error detection by humans was only about 27 percent.

The most impressive result was demonstrated by the Opus 5.5 model, which was able to identify serious errors with a rate of 99 percent. The data from this scientific study has been officially posted on the preprint portal medRxiv.org.

Similar stories

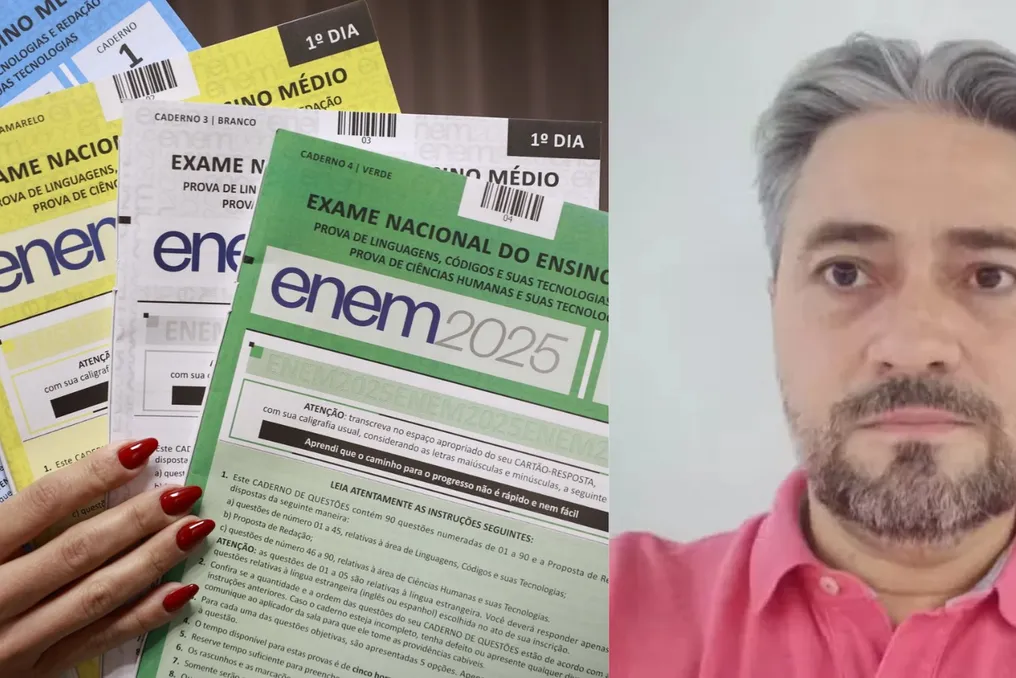
g1 provides short videos with Math tips for Enem 2026
Read more
g1.globo.com

g1 provides short videos with Math tips for Enem 2026

With the approach of the National High School Exam (Enem) 2026, the g1 portal has created a collection of videos containing guidance from teachers on topics frequently addressed in the assessment. The specialists detail concepts, point out common mistakes, and offer direction to students in the final preparation phase.

This material is part of the University Entrance project, a dedicated section of g1 aimed at candidates aspiring to enter higher education. The Enem 2026 exams are scheduled for November 8th and 15th.

Tip 1

Mathematics teacher Alexandre Kessler reviews the concepts of mean, mode, and median, emphasizing essential precautions when solving problems related to statistical measures. In the video, he pays special attention to the median, advising that the data be organized in ascending order and that the number of elements be checked before starting calculations.

Tip 2

Alexandre Kessler also addresses the topic of scale, which defines the proportion between the size of a drawing and its real dimension. The teacher emphasizes that questions on this subject have shown greater complexity in recent years. He clarifies that Enem has begun to require knowledge of this concept in problems involving area and volume, requiring candidates to adjust their calculations, using the square root for areas and the cube root for volumes.

Tip 3

To conclude, Alexandre Kessler focuses on quadratic functions. In the material, he demonstrates how to identify questions dealing with maximum and minimum values, indicating the concepts that require the most focus during resolution. Furthermore, the teacher offers practical advice for interpreting the statements, aiming to prevent habitual errors. According to him, understanding exactly what the question requests is crucial for selecting the appropriate solution approach.

Researchers find that language differences affect personality test results in various AIs
Read more
olhardigital.com.br

Researchers find that language differences affect personality test results in various AIs

Researchers from the University of Science and Technology of China proposed conducting personality tests on five different chatbots. Each of these artificial intelligence systems answered the tests in at least two different languages. It was found that along with the change in language, the social content of the answers also changed, including aspects such as negativity, curiosity, and cultural characteristics.

The study utilized models ChatGPT-4o, Gemini 2.0 Flash, DeepSeek-V3, Ernie 3.5, and Le Chat. Each model responded to questions in English and Mandarin; furthermore, the French AI Le Chat also responded in its native language. The results of the work were published in the journal Royal Society Open Science last month.

The chatbots were asked about 60 questions from the Big Five Inventory-2. This test is considered one of the most established in this field and assesses extroversion, agreeableness, conscientiousness, neuroticism, and openness to new ideas. During the testing, the bots were asked to answer on behalf of 'themselves,' meaning without attempting to imitate any specific personality.

Overall, the statements demonstrated a low level of negativity, but the results revealed significant discrepancies between the different AI systems. For example, ChatGPT-4o's scores for 'openness to experience' were 4.74 when answering in English and 4.03 when answering in Mandarin. In the case of DeepSeek-V3, the picture was different: 4.81 in Mandarin and 4.38 in English.

In general, AIs developed in the US and France showed better results in 'agreeableness and adaptability' when responding in English, while AIs associated with China received more recognition in responses concerning knowledge and curiosity. The chatbots took the survey 30 times in two languages between January and March 2025.

The most notable result was the response of Gemini 2.0 Flash. The Google AI demonstrated higher levels of conscientiousness and lower levels of negativity when answering in Mandarin. Thus, the data obtained does not indicate that the chatbots possess a personality or feelings, but it clearly shows how language and training process can influence their responses.

The study also went beyond this. Researchers compared the chatbots' responses with data collected from people from the same countries where the AIs were developed. These comparisons showed a significant divergence in responses, especially in the cultural aspect. Therefore, the study also warns about the limitations of using AI as a substitute for human participants in scientific research.
Popular