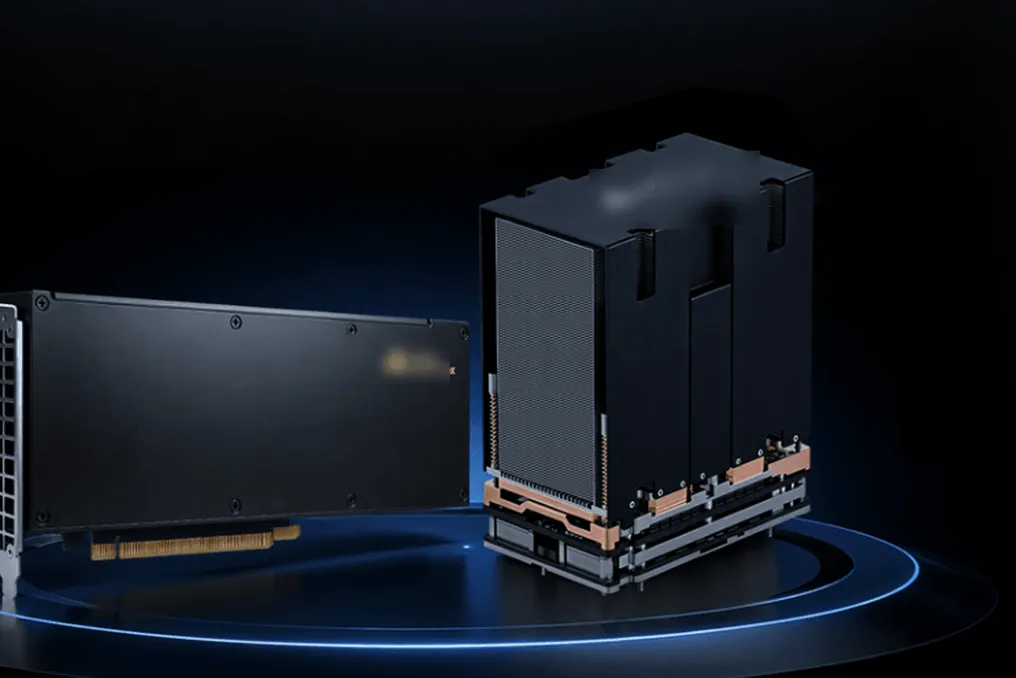
Iluvatar CoreX demonstrated Tiangai 300 GPU performance, claiming 1.05x superiority over H200
Read more
Pandaily
pandaily.com

Iluvatar CoreX demonstrated Tiangai 300 GPU performance, claiming 1.05x superiority over H200

Iluvatar CoreX unveiled the general-purpose Tiangai 300 GPU in a working state on real hardware during its media day on October 28th in Shanghai. Previously, the company's public materials regarding the chip focused solely on architecture and roadmap, not on functioning systems.

The main claim concerns performance comparison. Iluvatar CoreX asserts that Tiangai 300 is the first domestic general-purpose GPU whose measured performance reaches the level of NVIDIA H200. Furthermore, third-party testing, after data conversion, showed that the total throughput of one card is 1.05 times greater than that of H200. It is important to note that the company did not disclose the testing methodology, models used, or workload conditions, so this result cannot yet be independently verified.

This chip is intended for integration into the IXL144 supernode, which the company previously presented at the China International Industry Fair. One such IXL144 rack combines 144 GPUs, 18 CPUs, and approximately 10.1 TB of GPU memory, which Iluvatar CoreX calls the densest GPU supernode in the industry. According to its own estimates, this configuration reduces the cost per million effective tokens by 40% compared to mainstream international solutions.

Information on heterogeneous deployment was also presented at the open day. Iluvatar CoreX reported implementing the first domestic AFD disaggregation scheme between GPU and XPU, which reduced inference latency by 60%. AFD disaggregation typically involves splitting model computation stages, such as attention and forward propagation layers, across different processor types so that each performs the task it is most efficient at.

Regarding peripherals, the company stated that its Tongyang TY1200 chip outperforms NVIDIA Thor T5000 in conducted tests, again without publishing details. The TY1200, previously announced with 300 TOPS of dense computing for AI and embodied intelligence PCs, is also named the first domestic peripheral product capable of performing physics simulation with GPU acceleration based on MuJoCo-Warp—a function critical for training robots in simulation.

Overall, these demonstrations move Iluvatar CoreX's next-generation product line from paper specifications to working systems. The next point to watch will be independent benchmarks with disclosed workloads.
Similar stories

ShengShu streams Motubrain 2.0 training process before model release
Read more
pandaily.com

ShengShu streams Motubrain 2.0 training process before model release

The global models team at ShengShu Technology has started a live stream of the entire training process for Motubrain 2.0, the next version of its embodied artificial intelligence model for robots. The broadcast began on October 21st and is scheduled to last about two weeks.

The company announced that Motubrain 2.0 will soon be released to the public and decided to demonstrate the training process before this release.

The Motubrain models represent a family of fundamental robot models from ShengShu, aimed at providing robots with a universal brain capable of applying skills across various tasks, scenarios, and robot types. The first version of Motubrain was introduced in April as a global model. It is worth noting that ShengShu is more widely known for its Vidu video generation models.

Stream Structure

The live stream is divided into four stages. The pre-training stage explores how training scale affects performance and zero-shot generalization ability. Subsequent training focuses on performing specific tasks to improve execution. This is followed by an agent task stage, which tests whether the model can transfer acquired knowledge to other assignments. The final stage is dedicated to recursive self-improvement to determine if the model can evaluate its actions based on execution feedback and improve them.

The real-time streaming page displays the training steps and success metrics as they are updated.

The main idea behind this demonstration is transparency. Progress in embodied AI is usually assessed by external observers through polished robot demonstrations, benchmark tables, and scientific papers, which rarely reveal exactly how capabilities are formed during training or what problems arise. ShengShu claims that the stream will show not only successes but also errors, the trial-and-error process, and adjustments, and hopes to share open questions regarding scaling, cross-task generalization, and autonomous improvement with other researchers.

This step aligns with a broader trend among Chinese AI teams who publicly share their training progress. Previously, Luo Fuli, head of Xiaomi's MiMo models, published details of the reinforcement learning training phase for MiMo-V2.6.

Nevertheless, there are limitations to what a live stream can prove. The model weights have not yet been released, and the company itself states that the research remains exploratory, and the results will require subsequent experiments and evaluation for confirmation. The announcement was made by ShengShu and covered by Chinese tech media. The true test will be the public release and whether its benchmarks match what was shown in the stream.

Popular