Xiaomi has introduced MiDashengLM-Spatial, a new component of its Dasheng series of audio models. This model is designed not only to understand the content of sound but also its spatial origin.
The full model weights and inference code have been published by the company under the Apache 2.0 license, which permits both research and commercial use. The model is built upon MiDashengLM-7B, a large sound understanding model that Xiaomi previously made open source.
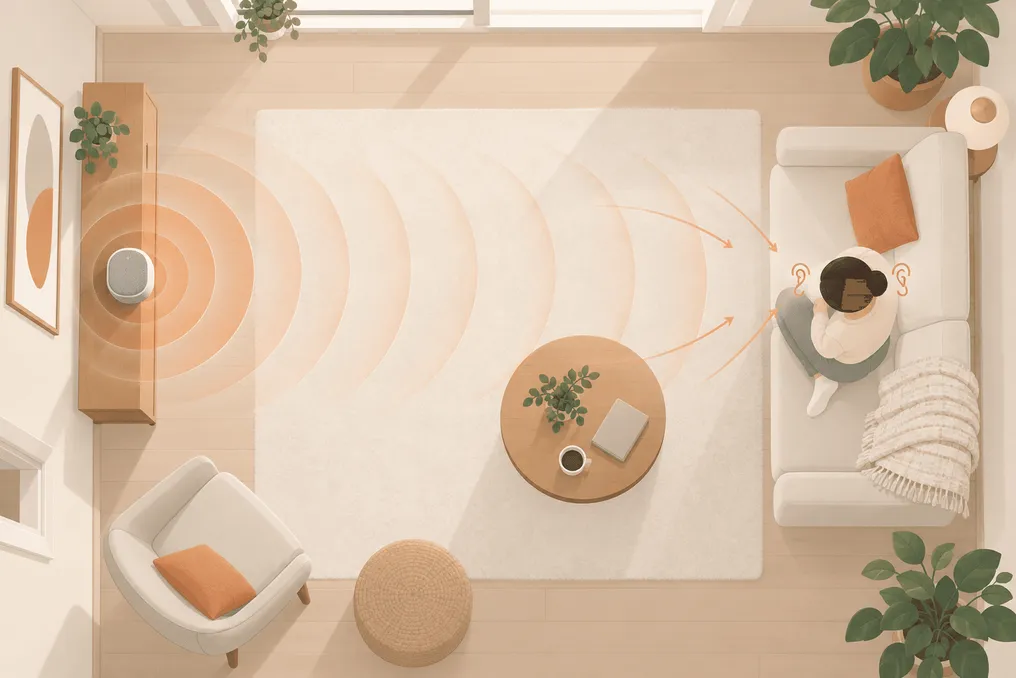
To enable spatial perception, a spatial audio encoder named Spatial-Dasheng was added to the model. According to a technical report posted on arXiv, it utilizes a hierarchical semantic-to-spatial conditioning module that separately captures semantic and spatial information before merging them. This results in a unified end-to-end model capable of analyzing speech, background noise, and music, as well as inferring the direction, distance, and movement of the sound source.
On the Hugging Face page, the model is presented with approximately 8 billion parameters. Spatial cues depend on multi-channel input; the model description states that it was trained on binaural two-channel audio, although mono input is also supported, it does not carry directional information.
Xiaomi asserts that the general audio capabilities of the model are preserved, and the research team reports that performance in basic audio processing tasks remains comparable to large audio-language models of around 8 billion parameters.
Xiaomi positions MiDashengLM-Spatial as the first open, end-to-end model for spatial audio understanding in the industry. It should be noted that this claim is contained within the article and qualified with the phrase 'to our knowledge,' and it has not yet been independently verified.
Over the past two years, Xiaomi has made its fundamental sound models, Xiaomi Dasheng and MiDashengLM-7B, open source. The company notes that technologies from the Dasheng series are already used in over 30 applications across its smart home and automotive cockpit products, covering speech recognition, ambient sounds, and music. This figure refers to the existing series, not the new MiDashengLM-Spatial model.
Regarding MiDashengLM-Spatial itself, Xiaomi plans to gradually integrate it into smart home and automotive cockpit scenarios, where knowing the origin of a voice or alarm signal will allow assistants to react more accurately. The company has not yet provided timelines or names of specific products.
The release includes a project demo page, a technical report on arXiv, evaluation code on GitHub, and model weights on Hugging Face.